Data ingestion for the real world
Connect your entire data stack, configure intelligent retries, and run custom backfills by table and endpoint.
14-day free trial. No credit card required.Trusted by data teams processing billions of rows every month


An open API to integrate with the rest of your stack
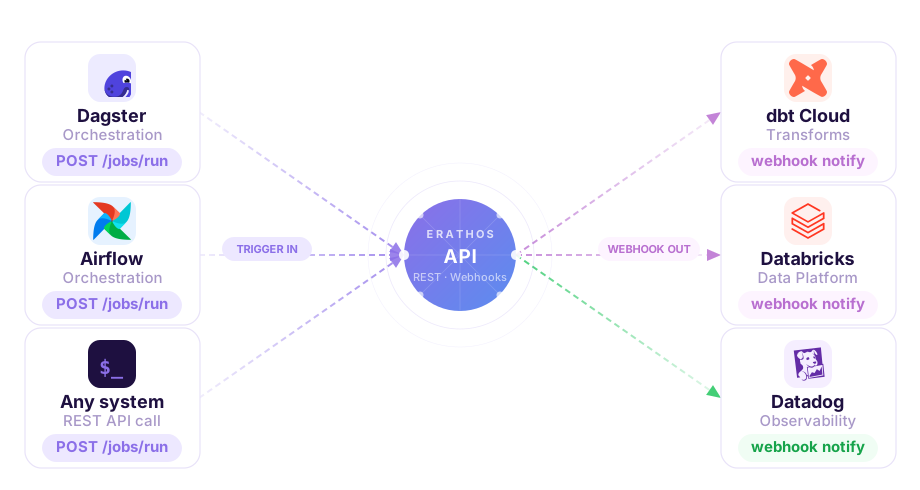
Plug data ingestion into the rest of your workflow. Trigger jobs in Databricks when ingestion finishes, orchestrate with Airflow or Dagster, and run dbt transformations once the data is ready.
Control down to the source that isn't in the catalog
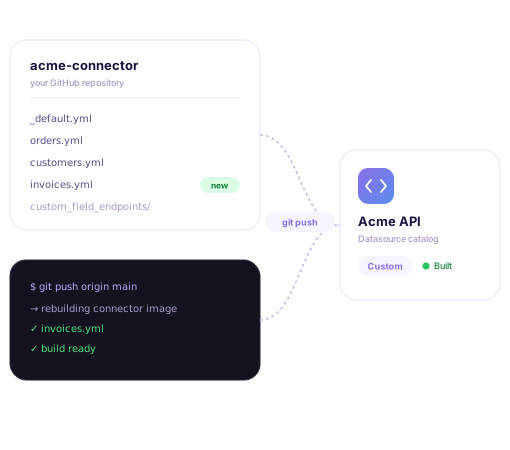
Internal APIs and niche software rarely make it into a public catalog. With the custom connector, you describe the source in YAML files in your own GitHub repository: authentication, pagination, fields, primary key and the incremental-sync cursor.
Erathos watches the repository and rebuilds the connector on every push. It shows up in your source catalog with the Custom badge, and the connection is set up like any other connector's. Available on the Pro and Enterprise plans.
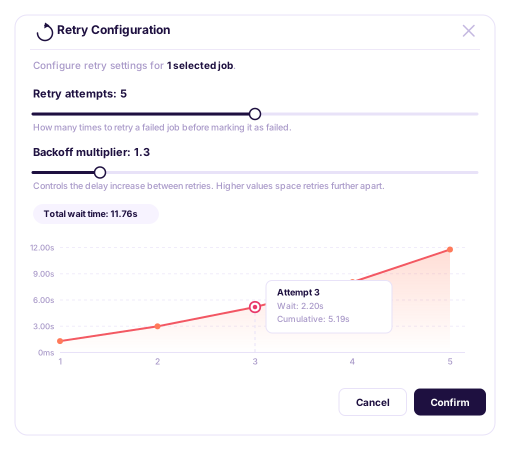
Configure the right retry for each API
Every API behaves differently. Some endpoints need aggressive retries. Others need larger backoff windows.
Erathos lets you define retry strategies at both the connection and job level, so pipelines recover from failures without overwhelming external systems.
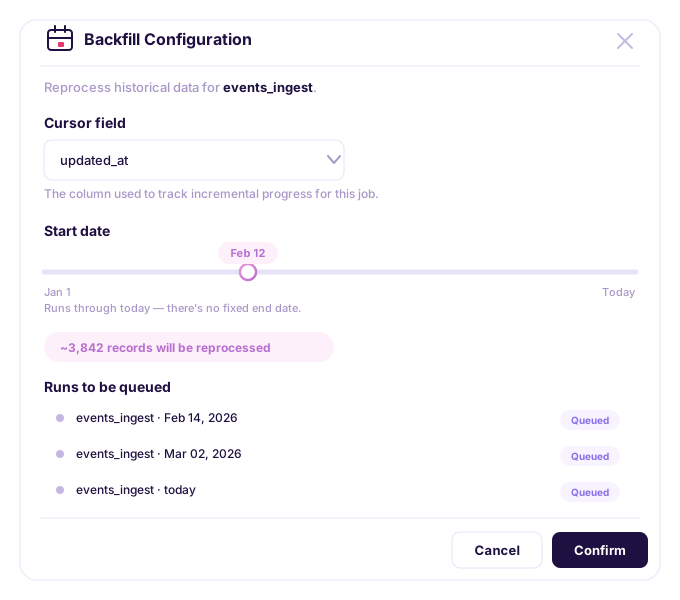
Reprocess historical data whenever you need to
Erathos lets you adjust cursors directly on job runs, making it easy to reprocess specific date ranges or recover from partial failures.
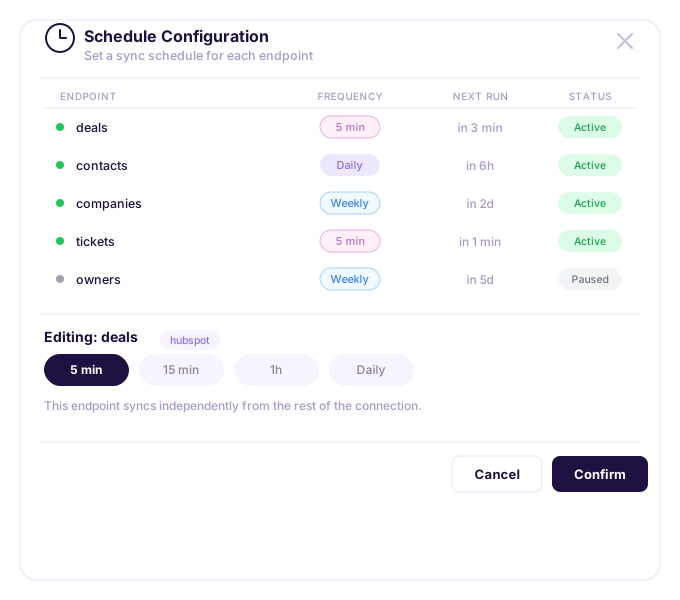
Schedule pipelines with precision
Most ingestion tools schedule pipelines at the source level. But APIs rarely behave uniformly.
Erathos lets you schedule by endpoint or table, so each dataset syncs at the frequency it actually needs.
Whoever loves data, loves Erathos.
“Every new source implementation, if I had to do it myself, would take about two or three months. With Erathos, it's done in a few hours. I don't need the skills of a data engineer to generate real value from the company's data.”

“Erathos revolutionized data management at WE. By integrating multiple SaaS tools into a single DW, our technical team now focuses on the core business. We implemented dashboards with insights across every area, enriching our organizational culture and improving our decision-making.”

“We used to have a lot of rework, and now we don't. It's more efficient to work this way. If it's not your core business, hire Erathos. Spend your time modeling your own domain, not someone else's.”

“If I didn't have this infrastructure, I'd need three or four people to do what Erathos does today. I was able to generate real value from my data with a much leaner setup than I thought I'd need. That's the core of building a data-driven culture: the team only uses data when they can trust it.”

“Erathos brought a practical turnaround at CCM. We were able to integrate financial systems, CRM, and processes with BigQuery in just a few clicks, with no technical team required. That gave us a reliable data warehouse that powers automations, dashboards, and even our customer service bots.”

“The robustness and efficiency of Erathos's connectors — whether for Meta, Google, RD Station, or ERPs like Bling and Conta Azul — make the whole process much faster and more reliable. The technical documentation is extremely well put together and intuitive, which makes implementation much easier.”







Frequently Asked Questions
It means being able to decide how each pipeline behaves, not just check whether the data arrived. It involves triggering and orchestrating jobs via API, defining retry strategies per connection or job, reprocessing specific stretches of history without reloading everything, and scheduling by endpoint or table instead of by the whole source.
Because ingestion without control turns into a black box. You only find out something went wrong once the data has already arrived incomplete or late at its destination. With control, you decide how each pipeline reacts to failures, fix history without depending on the tool's team, and adjust frequency to match each dataset's real needs.
With an open API to trigger and orchestrate jobs, retries configurable by connection or job, cursor-based backfill, and scheduling by endpoint — instead of leaving everything to a fixed default behavior.
Not necessarily. Erathos's defaults already cover most cases. You only step in when you want different behavior for a specific endpoint or job.
Internal APIs and niche software are what the custom connector is for, on the Pro and Enterprise plans. You describe the source in YAML in your own GitHub repository and install the Erathos app on it. Every push rebuilds the connector, and it shows up in the catalog with the Custom badge. If you'd rather, a coding agent can build the connector for you. The walkthrough is in the custom connector docs.
Every run is logged with what ran, when, and with what result — including retries, failures, and reprocessing. It's control and observability together.